

Everyone’s buying Nvidia.
Meanwhile, the companies that will 10–100× over the next three years are hiding in plain sight — in memory fabs, laser factories, and power equipment backlogs that most investors have never heard of.
I just taught the first live class of my free AI Investing Bootcamp — a course focused on investing in AI stocks from a technical perspective, covering the AI fundamentals every investor needs to know. Future classes will go deep on AI tools, workflows, prompt engineering, and hands-on sessions with Claude Code, Codex, and more with the selected group of 10 people.
Thanks for reading AI tools for investing! Subscribe for free to receive new posts and support my work.
This post is the core thesis from Class 1.
If you only remember one thing: the bottleneck is the investment thesis.
First, the basics — what actually happens inside a data center
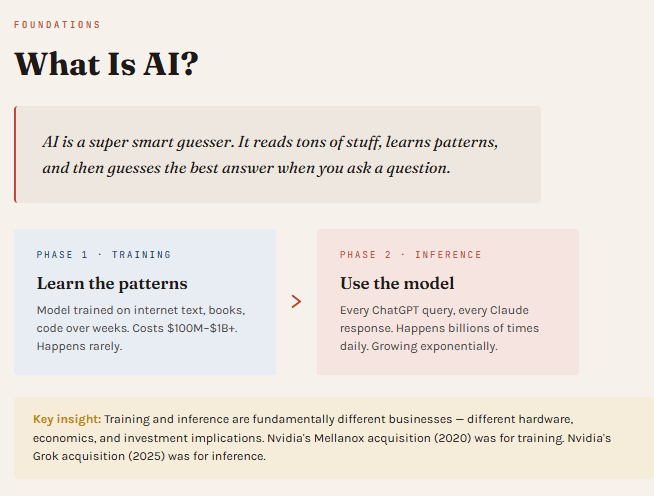
AI has two phases. Understanding the difference is the entire foundation.
Training is where a model learns. It reads the internet, books, and code over weeks or months. It costs $100M to $1B+. It happens rarely — maybe once every year or two per frontier model.
Inference is where the model works. Every time you ask ChatGPT a question or Claude writes code, that’s inference. It happens billions of times daily and it’s growing exponentially.
Training and inference are fundamentally different businesses with different hardware, different economics, and different investment implications. Nvidia’s Mellanox acquisition in 2020 was a training play. Their reported interest in inference-focused companies tells you where the puck is going.
Both require massive capital expenditure. Both are bottlenecked. And those bottlenecks are where the opportunity lives.
Bottleneck 1: The Memory Wall
Here’s the number that should keep GPU investors up at night.
Since 2010, compute power (raw FLOPS) has grown 60,000×. Memory bandwidth? About 100×. Interconnect speeds? Roughly 30×.
A modern GPU can do trillions of calculations per second. But it spends most of its time waiting — waiting for data to arrive from memory. The chip is literally starving.
This isn’t a bug. It’s physics. And it creates an enormous investment opportunity.
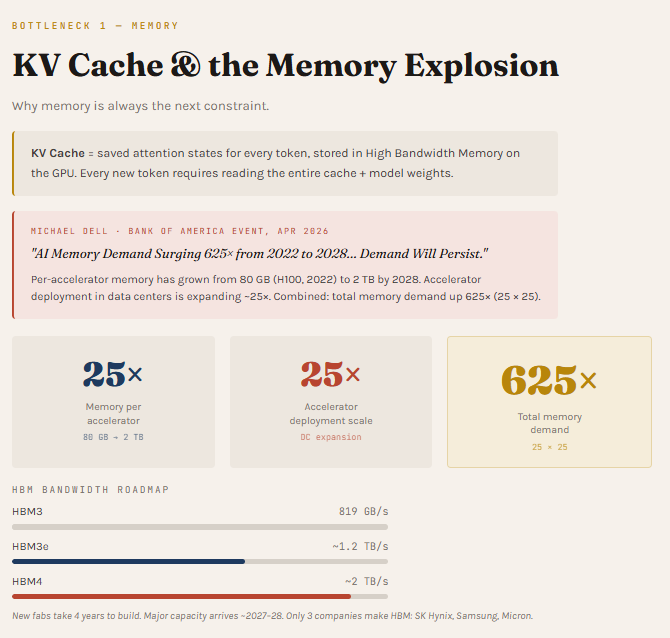
Michael Dell said it plainly at a Bank of America event in April 2026: AI memory demand is surging 625× from 2022 to 2028. That’s not a typo. Per-accelerator memory is growing from 80 GB to 2 TB (25×), and accelerator deployment is expanding roughly 25× as well. Multiply them together: 625×.
Only three companies on Earth manufacture HBM (High Bandwidth Memory): SK Hynix, Samsung, and Micron. New fabs take four years to build. Major new capacity doesn’t arrive until 2027–28.
Do the math on a 625× demand surge with a four-year supply lag.
Bottleneck 2: The CPU Shortage Nobody’s Talking About
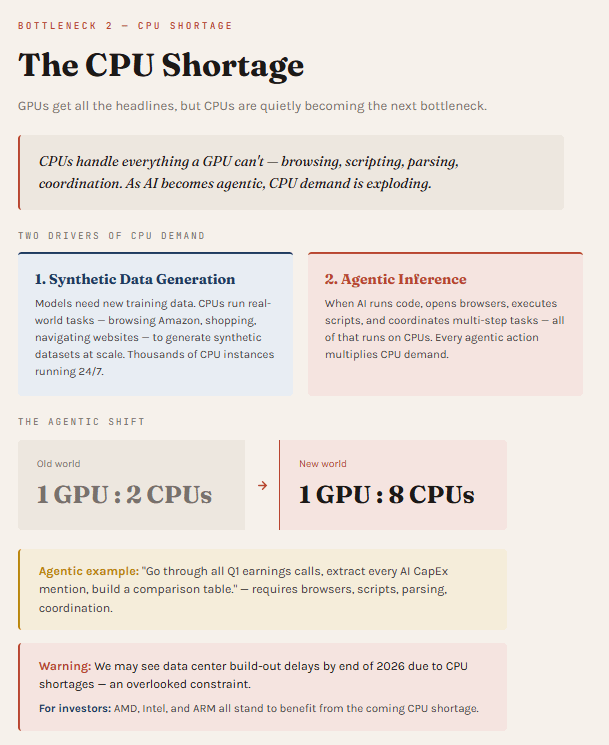
GPUs get all the headlines. But CPUs are quietly becoming the next constraint.
Why? Two reasons.
First, synthetic data generation. Models need new training data, and one of the best sources is synthetic — CPUs running real-world tasks like browsing websites, shopping on Amazon, and navigating apps to generate datasets at scale. Thousands of CPU instances running 24/7.
Second, agentic inference. When AI runs code, opens browsers, executes scripts, and coordinates multi-step tasks, all of that runs on CPUs. Every agentic action multiplies CPU demand.
The old ratio was roughly 1 GPU to 2 CPUs. In the agentic world, it’s heading toward 1 GPU to 8 CPUs. AMD, Intel, and ARM all stand to benefit from a constraint most investors aren’t pricing in yet.
Bottleneck 3: The Optics Revolution
This one is almost entirely off most investors’ radars.
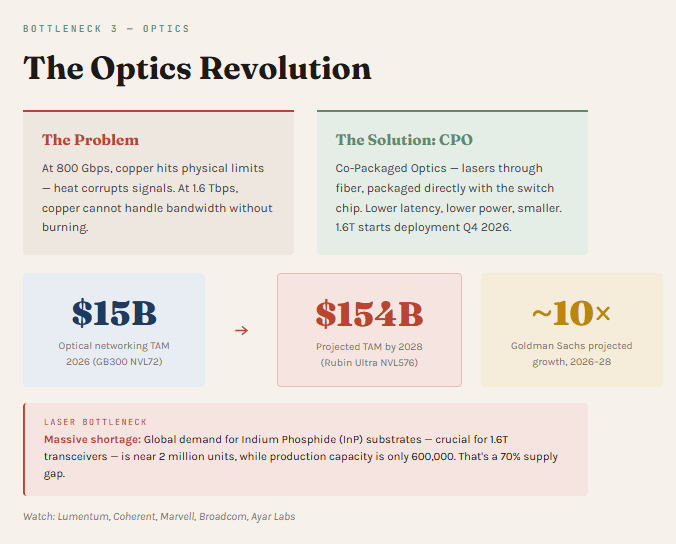
At 800 Gbps, copper cables hit their physical limits — heat corrupts the signal. At 1.6 Tbps (where next-gen data centers are headed), copper simply cannot function. It burns.
The solution is Co-Packaged Optics (CPO) — lasers through fiber, packaged directly with the switch chip. Lower latency, lower power, smaller footprint. Deployment of 1.6T systems begins Q4 2026.
The market numbers are staggering. Goldman Sachs projects the optical networking TAM growing from roughly $15B in 2026 to $154B by 2028. That’s approximately 10× in two years.
But here’s the real kicker: there’s a massive supply shortage. Global demand for Indium Phosphide substrates — critical for 1.6T transceivers — is approaching 2 million units. Production capacity? 600,000. That’s a 70% supply gap and the rerating of Sivers Semiconductor
Companies to watch: Lumentum, Coherent, Marvell, Broadcom, Ayar Labs.
Bottleneck 4: The 800V Power Problem
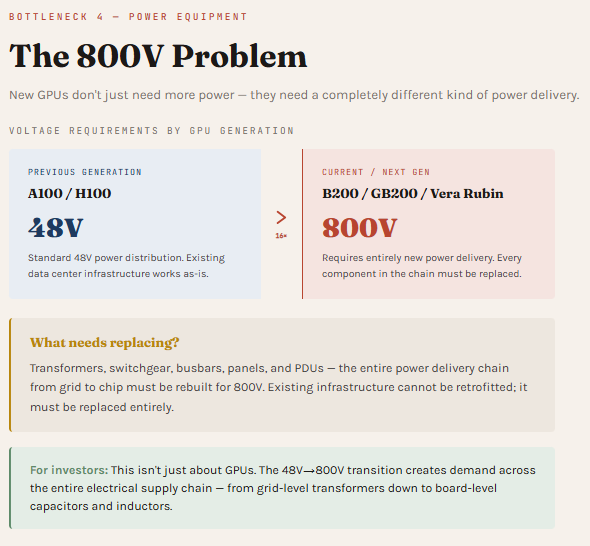
Previous-generation GPUs (A100, H100) ran on standard 48V power distribution. Existing data center infrastructure worked as-is.
New GPUs — the B200, GB200, and upcoming Vera Rubin — require 800V.
That’s not an upgrade. It’s a complete teardown.
Every transformer, switchgear unit, busbar, panel, and power distribution unit in the data center must be replaced. The entire power delivery chain from grid to chip must be rebuilt. Existing infrastructure cannot be retrofitted.
This creates demand across the full electrical supply chain — from grid-level transformers down to board-level capacitors (MLCCs) and inductors. ABB, Schneider Electric, Vertiv, Eaton, Murata, TDK — all of these become critical links.
Bottleneck 5: Power Itself
Data centers can’t wait four years for grid connections. They need power now.
Each GPU generation demands more. A100 clusters needed roughly 6 kW per GPU and 40 MW per campus. B200 and GB200 clusters need 15 kW per GPU and 300 MW per campus. Vera Rubin and beyond? 20+ kW per GPU, 500 MW+ campuses.
Hyperscalers are getting creative. Natural gas fuel cells (Bloom Energy) are being deployed as immediate backup because they face far fewer permitting hurdles than new grid connections. Backup generators from Siemens, GE, and Caterpillar have five-year backlogs.
One important note for investors: ignore “data center cancellation” headlines. Hyperscalers routinely file permits in three or four states simultaneously, knowing most will be denied. When three out of four get cancelled, that’s not a demand signal — it’s how the process works. The one that gets approved still represents massive spend.
The revenue is real
The most common bear case is that AI spending is irrational — that companies are pouring billions into infrastructure with no return.
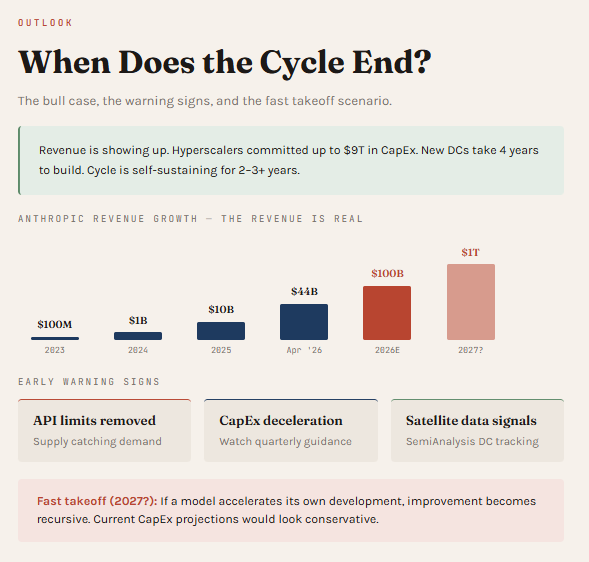
Look at the numbers. Anthropic went from $100M in revenue in 2023 to $1B in 2024 to $10B in 2025, reaching a $44B valuation by April 2026. Hyperscalers have committed up to $9T in cumulative CapEx. New data centers take four years to build.
The cycle is self-sustaining for at least two to three more years. The early warning signs to watch: API rate limits being removed (supply catching demand), CapEx guidance deceleration in quarterly earnings, and satellite-based data center tracking from firms like SemiAnalysis.
The framework
Here’s the simplest investing framework I can give you:
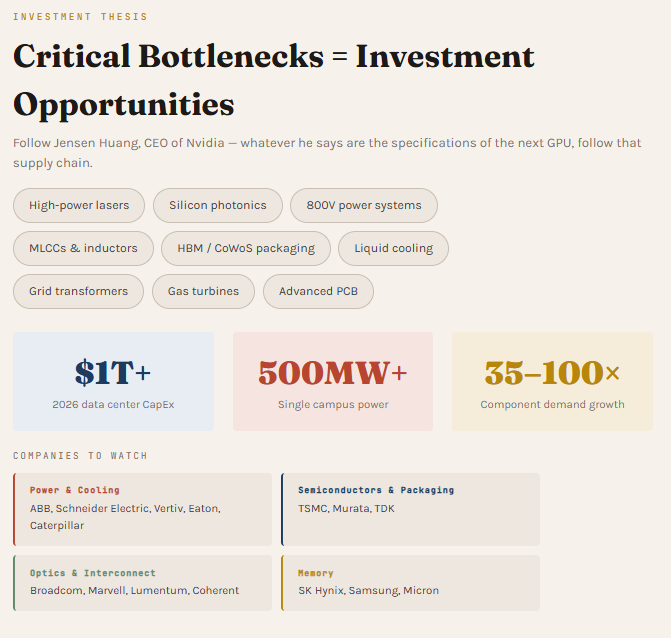
Follow Jensen Huang. Whatever he says are the specifications of the next Nvidia GPU — follow that supply chain. Every new spec creates demand for components that only a handful of companies can supply.
The bottleneck categories: high-power lasers, silicon photonics, 800V power systems, MLCCs and inductors, HBM and CoWoS packaging, liquid cooling, grid transformers, gas turbines, and advanced PCBs.
2026 data center CapEx is on track to exceed $1T. Component demand growth across these categories ranges from 35× to 100×.
What’s next
This was just Class 1 of the Bootcamp — the technical foundation. Future classes cover mastering AI prompts and workflows, building investing workflows with AI, hands-on sessions with Claude Code and Codex, and ultimately building your own personalized investment dashboard. I would all the slides and learnings through the email.
Subscribe to AI Tools for Investing to follow along.
Thanks for reading AI tools for investing! Subscribe for free to receive new posts and support my work.
And if this post was useful — share it with one investor friend who’s still only looking at Nvidia.
The real money is in the bottlenecks.